Hello, I'm

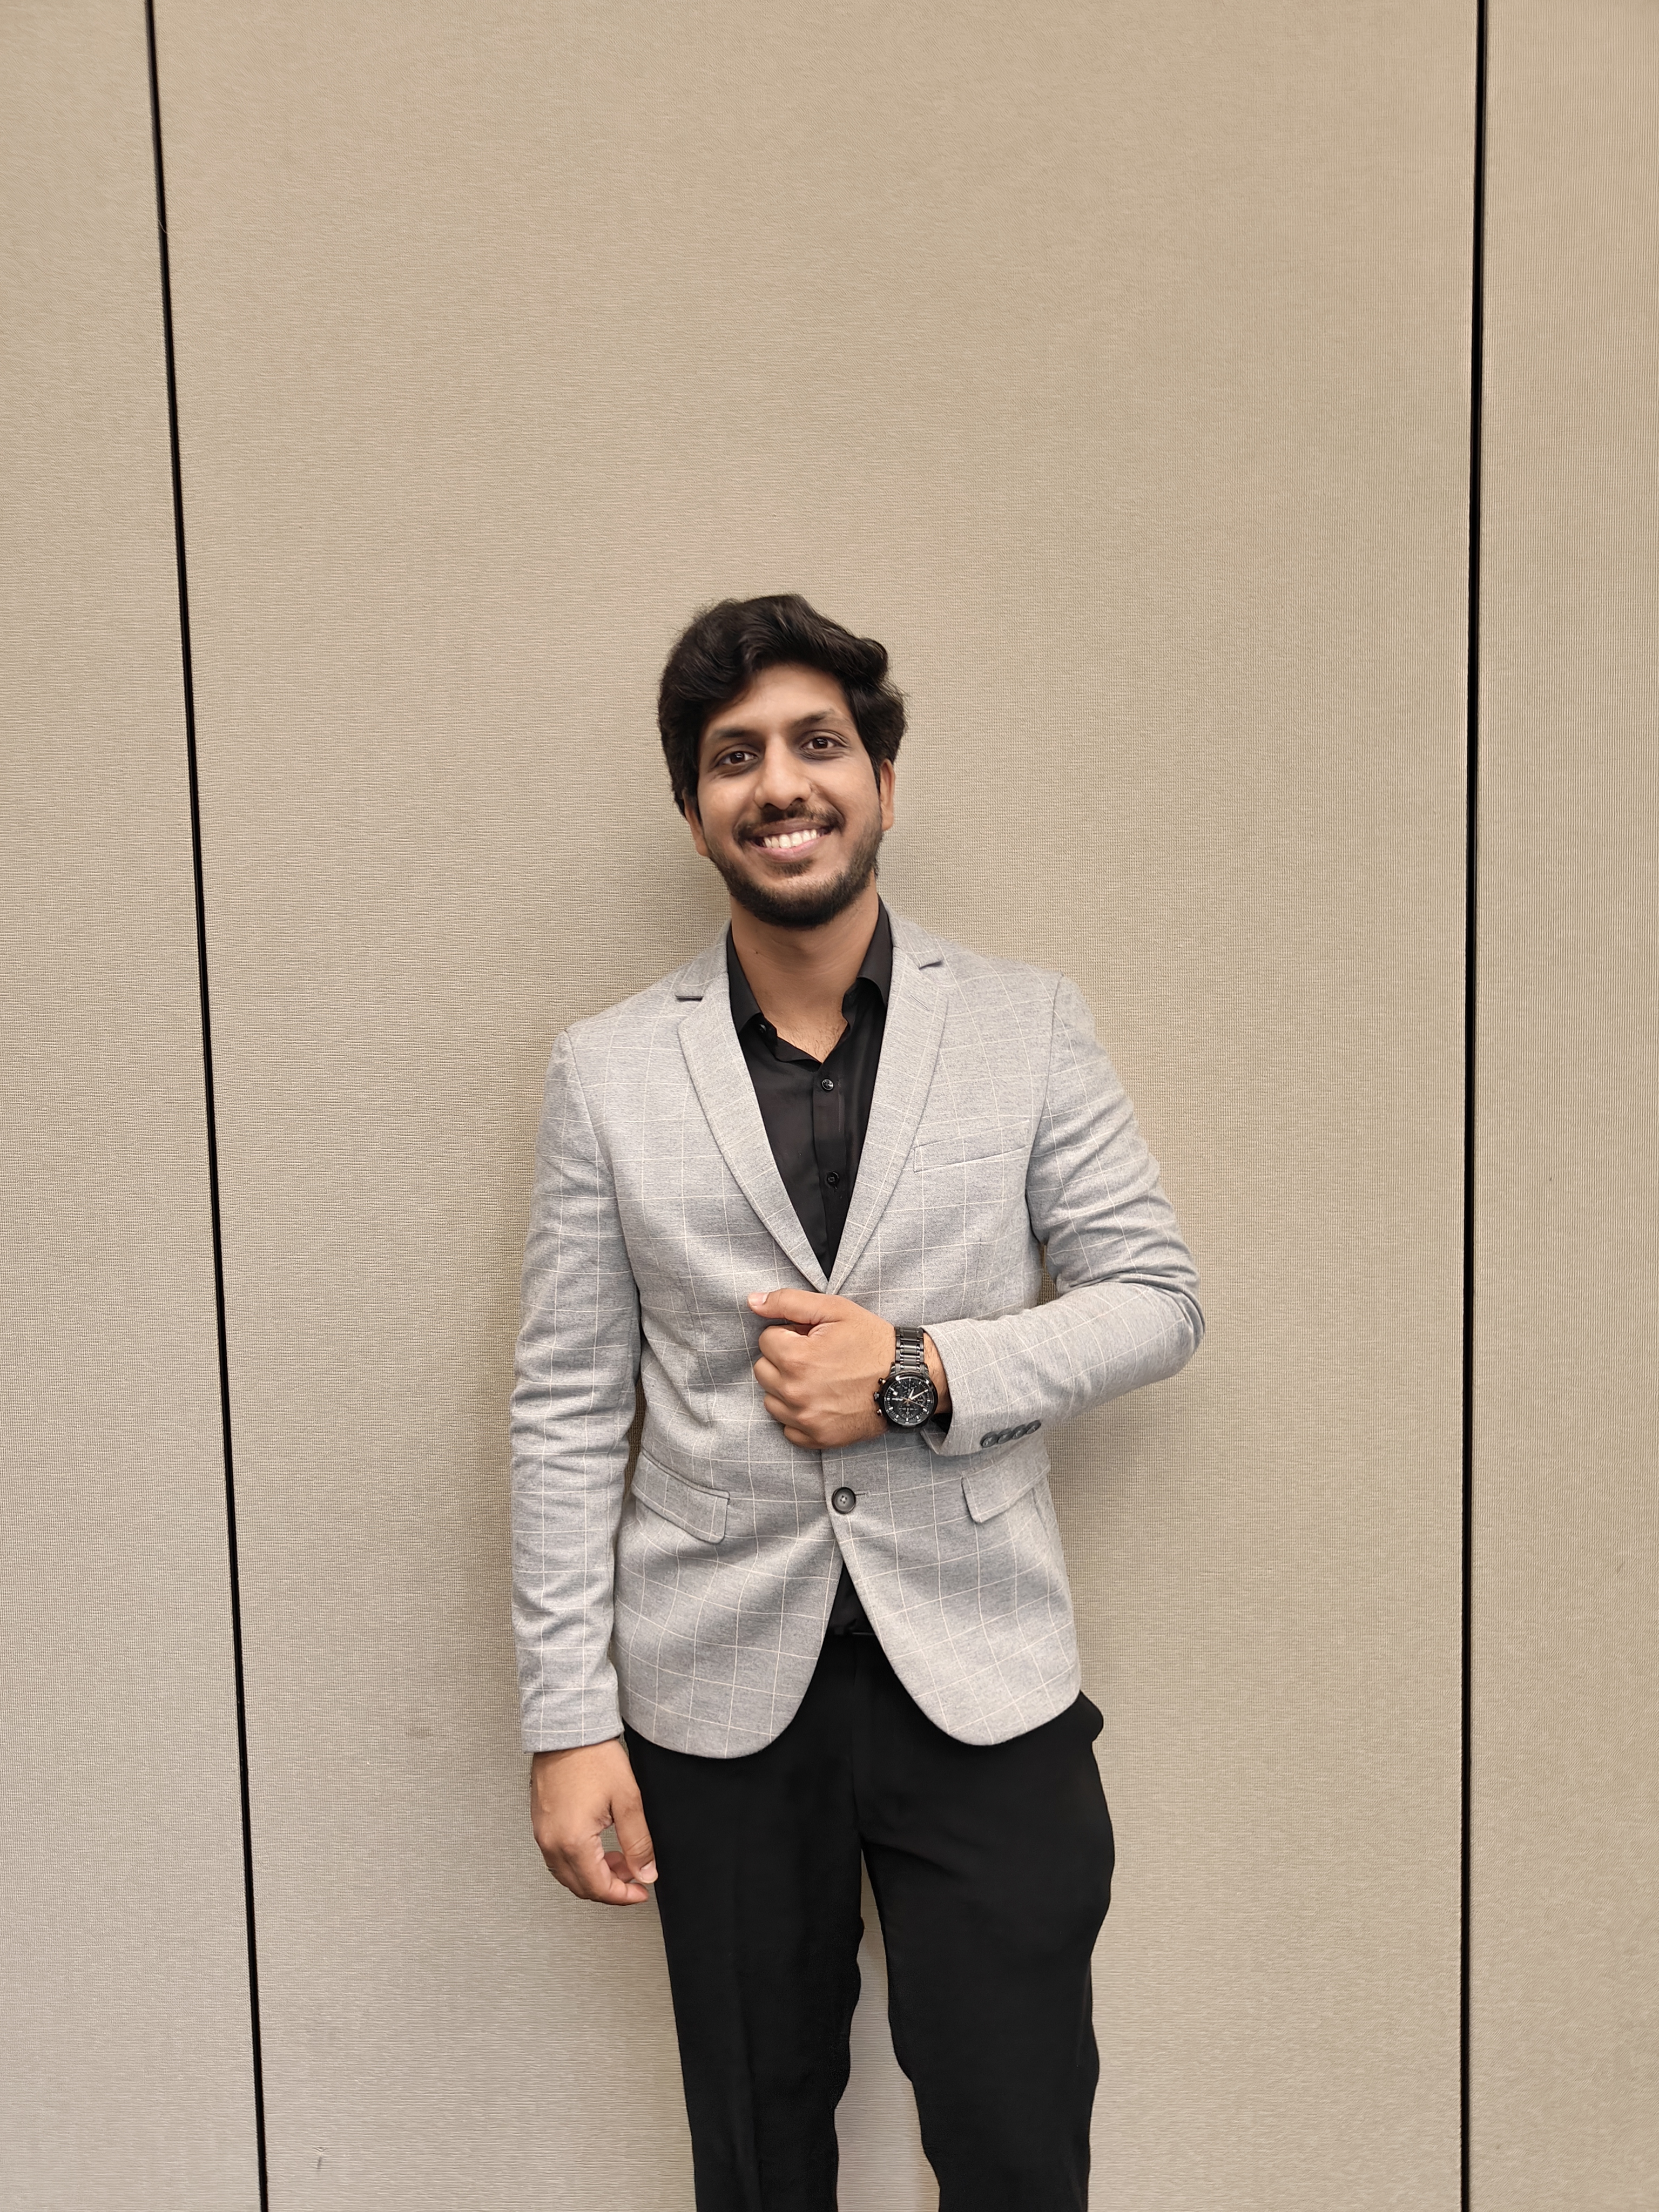
Saurabh Chauhan

I completed my Master of Science in Computer Science at the University of Illinois Springfield (May 2026, GPA 3.8), building on my Bachelor of Engineering in Computer Engineering from Pune University. Now based in Denver, CO, I am an AI Engineer at MedLaunch Concepts building LLM-powered healthcare AI products. With 4+ years of hands-on experience in AI/ML engineering, I have built and deployed production-grade systems from RAG pipelines and multi-agent LLM workflows to computer vision serving thousands of users with measurable business impact.

Work Authorization: Currently on OPT (started June 2026). Eligible for STEM OPT extension with 3 years total US work authorization.

About Me

Saurabh Chauhan - AI/ML Engineer & Software Engineer

AI/ML Engineer

I'm currently pursuing my M.S. in Computer Science at the University of Illinois, building on my B.E. in Computer Engineering from Pune University. With 3+ years of specialized experience in artificial intelligence and machine learning, I've successfully developed and deployed production-grade AI systems that have driven measurable business impact.

At MedLaunch Concepts in Denver, I'm building an LLM-powered accreditation & quality-management (QMS) agent that helps hospital quality teams work through complex regulatory standards. I architect the agent with the Claude SDK on AWS Bedrock, design retrieval over regulatory-standard and policy knowledge bases, and ship responsible-AI guardrails, including a citation-verification gate that stops fabricated regulatory citations from reaching users, plus latency and cost optimizations profiled from real production traffic.

My expertise spans the entire machine learning lifecycle from data preprocessing and feature engineering to model development, optimization, and production deployment. At Product Dossier Solutions (Kytes), I architected a production RAG system using LangChain, Mistral-7B, and FAISS that serves 10,000+ users across six enterprise clients with 95% query accuracy and sub-50ms retrieval latency. I have built AI inference APIs using gRPC integrated with Spring Boot microservices, handling 110,000+ daily requests with 99.5% uptime. I specialize in TensorFlow, PyTorch, LangChain, and deploying ML models on cloud platforms (AWS, GCP) to serve thousands of concurrent users.

Backend Engineer

I'm currently pursuing my M.S. in Computer Science at the University of Illinois, building on my B.E. in Computer Engineering from Pune University. With 3+ years of hands-on experience in backend development and distributed systems, I've architected and delivered scalable, high-performance applications serving thousands of users.

At MedLaunch Concepts in Denver, I'm building the backend for a healthcare accreditation/QMS AI agent: streaming LLM inference over AWS Bedrock, serverless data loaders, and a multi-tool orchestration layer with proper validation, error handling, and timeout controls. I focus on reliability and performance: eliminating silent hangs in streamed responses and shipping caching and prefetch optimizations that cut redundant serverless calls and model round-trips per request.

I excel in building robust backend systems with Java Spring Boot, Django, and FastAPI, specializing in microservices architecture, gRPC, and RESTful APIs. At Product Dossier Solutions (Kytes), I built high-throughput distributed systems handling 110,000+ daily requests through Spring Boot microservices communicating via gRPC and REST, implementing load balancing, Redis caching, and asynchronous queues to reduce response time by 40%. I developed an automated deployment system that reduced deployment time by 67%, supporting 10+ daily deployments. At Dasha Krit Technology (D10X), I architected a multi-tenant SaaS platform from scratch using Django and PostgreSQL, designing custom authentication, FSM-based workflow management, and RESTful APIs supporting 10+ models deployed to GCP serving 10+ enterprise clients.
4+
Years Experience
10+
Projects
10+
Technologies

Technical Skills

🤖 AI/ML Frameworks

TensorFlow 2.16 PyTorch 2.6 LangChain 2.0 LangGraph Claude SDK Scikit-learn OpenAI API RAG Hugging Face spaCy NLTK

💻 Programming Languages

Python 3.12+ (Advanced) R 3.6 SQL Java 11 C++ TypeScript

🌐 Web & Frameworks

FastAPI Flask Streamlit Django React.js Next.js

☁️ Cloud & Infrastructure

AWS (ECS, EKS, EC2, S3, Lambda, Bedrock, SageMaker) GCP Docker Kubernetes CI/CD (Jenkins, GitHub Actions)

🗄️ Database & Caching

PostgreSQL SQLAlchemy SQL Server 2019 Oracle Redis MongoDB Vector Databases (FAISS, ChromaDB)

📊 Data Science & MLOps

Pandas NumPy Apache Airflow PySpark MLflow

🎓 Certifications

AWS Machine Learning Essentials (Nov 2025) AWS Essentials (Jun 2024)

Work Experience

June 2026 - Present

AI Engineer

MedLaunch Concepts - Denver, CO
  • Healthcare Accreditation AI Agent: Building an LLM-powered agent that helps hospital quality teams navigate accreditation and quality-management (QMS) workflows, architected with the Claude SDK on AWS Bedrock (HIPAA-compliant, BAA) over regulatory-standard and policy knowledge bases with a multi-tool retrieval-and-reasoning pipeline.
  • Responsible-AI Guardrails: Shipped a citation-verification gate that flags fabricated or unverifiable regulatory standard codes before they reach users, using hierarchical standard matching and session-scoped grounding to eliminate hallucinated citations, the most critical class of accreditation error.
  • Performance & Cost Optimization: Profiled production traffic and shipped evidence-ranked latency fixes (result caching, schema prefetch) that removed redundant serverless calls and model round-trips; benchmarked alternative foundation models to cut per-call inference cost while preserving tool-routing accuracy.
  • Healthcare AI Backend: Building the backend for an LLM-powered accreditation/QMS agent: streaming inference over AWS Bedrock, serverless (Lambda) data loaders, and a multi-tool orchestration layer with validation, error handling, and timeout controls.
  • Reliability & Performance: Bounded idle gaps in the streaming model response to eliminate silent hangs, and shipped caching and prefetch optimizations that cut redundant serverless calls and model round-trips per request, measurably reducing latency.
2023 - 2024

Software Engineer (AI-ML)

Product Dossier Solutions Pvt. Ltd.
  • Production RAG System: Architected enterprise RAG system using LangChain, Mistral-7B, and FAISS, integrated with RASA chatbot to serve 10,000+ users across six enterprise clients with 95% query accuracy and sub-50ms retrieval latency.
  • Distributed ML Pipeline: Migrated legacy single-threaded Apache Airflow DAGs to distributed PySpark architecture, enabling parallel execution that reduced data processing time by 65% for enterprise project management platform.
  • ML Microservices: Built AI inference APIs using gRPC integrated with Spring Boot microservices, handling 110,000+ daily requests with intelligent caching and load balancing, achieving 99.5% uptime.
  • Vector Database Implementation: Implemented FAISS vector database for semantic document search, processing 200+ PDFs per client with optimized embedding generation and sub-50ms retrieval latency.
  • Microservices Architecture: Built high-throughput distributed systems handling 110,000+ daily requests through Spring Boot microservices communicating via gRPC and REST, implementing load balancing, Redis caching, and asynchronous queues to reduce response time by 40%.
  • Deployment Automation: Implemented automated deployment system for PSA platform using Obevo and Apache Freemarker, reducing deployment time by 67% and supporting 10+ daily deployments with 5+ monthly production releases.
  • API Gateway Integration: Integrated Apache APISIX gateway with JWT authentication, rate limiting (1000 req/min), and load balancing, reducing API latency by 40% and eliminating security vulnerabilities.
  • CI/CD Pipeline: Engineered Docker-based CI/CD pipeline with Jenkins, enabling 50+ monthly zero-downtime releases with 100% success rate.
2021 - 2023

Software Engineer

Dasha Krit Technologies Pvt. Ltd. (D10X)
  • SaaS Architecture: Programmed a Django multi-tenant workflow application from scratch, contributing 70% to the core codebase and leading the system design.
  • Data Automation: Created automated data pipelines using Python and SQLAlchemy to ingest daily NIFTY 50 market data, providing clients with immediate access to historical datasets for strategy backtesting and paper trading.
  • Test Automation Framework: Developed comprehensive test automation framework with 100+ test cases using Robot Framework and Playwright, reducing QA cycle time by 60% through data-driven testing methodology.
  • SaaS Architecture: Programmed a Django multi-tenant workflow application from scratch, contributing 70% to the core codebase and leading the system design.
  • Database Engineering: integrated daily updates into the database via SQLAlchemy ORM, optimizing query performance for live data feeds.
  • Real-time Systems: Developed a Fintech product architecture integrating third-party APIs and WebSockets for real-time stock market data processing.
  • DevOps: Created shell scripts to automate software deployments and manage Linux server configurations.
  • Test Automation: Developed comprehensive test automation framework with 100+ test cases using Robot Framework and Playwright, ensuring full feature coverage and reducing regression testing time by 60%.

Featured Projects

🤟

ASL to Text Recognition

Problem: Real-time American Sign Language translation using computer vision and deep learning.

Solution:
Fine-tuned VideoMAE transformer on 239-class ASL dataset, improving accuracy from 62% to 82% (+32% improvement) through novel Universal Temporal Sub-sampling technique optimized for GPU-constrained training. Implemented AdamW optimizer and cosine learning rate decay for optimal convergence. Supports multi-sign prediction from long-form videos with temporal context awareness.

Python PyTorch VideoMAE Hugging Face Computer Vision
🏛️

Montgomery AI Navigator Hackathon

Problem: Montgomery County residents struggle to navigate complex government services and information.

Solution:
Built a Retrieve-Reason-Validate multi-agent pipeline using LangGraph and Google Gemini 2.5 Flash that decomposes queries, retrieves county-specific information, reasons over it, and validates answers before responding. React 18 + TypeScript frontend with FastAPI backend, designed and shipped end-to-end in a 24-hour hackathon.

Python LangGraph Gemini 2.5 Flash FastAPI React 18 TypeScript
🔬

Research Assistant (Multi-Agent AI System)

Problem: Standard RAG systems perform single-chain retrieval with no source credibility evaluation or confidence scoring, producing unreliable research outputs.

Solution:
Built a production-grade multi-agent research system using AutoGen where specialized agents divide the pipeline - one retrieves and searches sources, a second evaluates credibility and assigns confidence scores, and a third synthesizes structured outputs with executive summaries, consensus/disagreement analysis, and numbered citations. Deployed on Amazon EKS with two replicas per service, ALB ingress, and zero-downtime rolling deployments representing a complete MLOps workflow.

Python AutoGen LangChain Mistral-7B FastAPI React Docker AWS EKS
🧠

Neurofinity

Problem: Long meeting transcripts are hard to digest, especially for neurodivergent users who benefit from visual structure.

Solution:
Fine-tuned Flan-T5 with LoRA/PEFT on meeting transcripts to auto-generate hierarchical mind maps, deployed as a FastAPI + Streamlit app with neurodivergent accessibility controls (contrast, spacing, themes). Built a custom structural evaluation framework measuring tree-edit similarity and hierarchical depth.

Python Flan-T5 LoRA/PEFT FastAPI Streamlit Hugging Face

Get In Touch

📍

Location

Denver, Colorado

📱

Phone

+1 (217) 862-4640